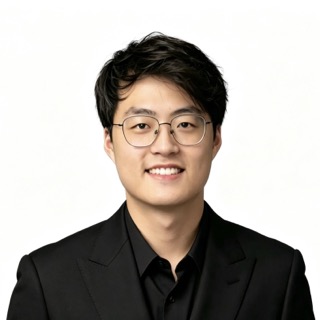
Terence Zhang
software engineer · AI research engineer
available for interesting problems- Previously
- SDE II @ Amazon
AI Research Engineer @ Vicino AI
Founding Engineer @ Bili Technology - Studying
- Cornell Tech · CS, MEng '27Merit Scholarship
- Studied
- Cornell University · CS & Economics, '22
terence@terenceOS:~$ whoami
Terence Zhang — software engineer & AI research engineer
Systems at scale.
terence@terenceOS:~$ cat about.txt
I build AI tools and distributed systems: enterprise AI marketing at Vicino AI, version control infrastructure for AI agent collaboration at Bili, and billion-scale digital asset management at Amazon.
terence@terenceOS:~$ ls
Try help, projects, experience, resume — or press ⌘K for the command palette. Everything here is also one click away in the navigation.
~/about/about.txt
Terence Zhang
software engineer · AI research engineer
About
I build systems where engineering meets a real user need — from generative AI tooling to infrastructure that holds up at billion-item scale.
SDE II @ Amazon: billion-scale distributed systems for digital asset management.
AI Research Engineer @ Vicino AI: Enterprise AI Marketing Platform.
Founding Engineer @ Bili: version control infrastructure for AI agent collaboration.
Academic and Campus Engagement
At Cornell, I studied Computer Science and Economics, taught courses across the CS curriculum, and built with teams that connected engineering to the physical world.
- Cornell UniversityCS & Economics · '22
- Cornell TechComputer Science · '27
- Campus workCMSX Backend Lead · Cornell Cup Robotics · CIS TA
- HonorsOmicron Delta Epsilon · Dean's List ×3
Elsewhere
~/projects
Selected projects
Systems I designed and built at Amazon, and products of my own where engineering meets a real user need.
- amazon/
- personal/
~/projects/amazon/source
Amazon · 2023–2025 · design author & lead engineer
Source: a deterministic lineage layer under 44 billion original images.
The data and ingestion architecture that stores, sanitizes and indexes every original upload at full fidelity, with two-way lineage to every variant made from it. It replaced eventually consistent index queries with deterministic key lookups inside a live upload pipeline.
- original assets stored, sanitized and indexed
- 44B+
- new originals per year
- 6–7B
- database write and storage overhead
- 3× → 1×
- failed storage requests per 90 days, resolved
- ~800K
01 / architecture
How it works
- New
- Changed
- Unchanged
- Removed from the lookup path
- 1Deterministic compound keyRecords are keyed on a 160-bit SHA-1 hash plus file type, in one strongly consistent lookup before any processing. Adding the file type resolves zero-byte and cross-format collisions.
- 2Sanitize once, inherit everywhereGPS and other sensitive EXIF data are scrubbed at upload. Fixed attributes (aspect ratio, moderation flags, AI-generation markers) are extracted once and inherited by every variant, with no repeated compute.
- 3Atomic distributed lockA conditional write acts as a per-record lock, so parallel uploads of the same file produce exactly one record and one stored object, with no race conditions.
- 4Prefix-partitioned storageThe first 4 hex characters of the hash spread files over 65,536 prefixes. This resolved the staging bottleneck behind ~800,000 failed requests in 90 days.
- 5Bidirectional lineageNested source-to-variant maps plus a transformation history let you trace both ways, from an original to every thumbnail, localized graphic and compressed web format, and back.
- 6Backfill billions of originalsEvery existing original is converted into a record, and duplicate copies left by older bugs are merged along the way.
02 / trade-offs
Trade-offs, measured
Choosing the fingerprint
Records needed before a 50% chance of a collision (log scale)
MD5 would already be past a coin-flip chance of a collision at this catalog size. SHA-1 removes that risk for 20% more compute; SHA-256's extra attack resistance doesn't matter for deduplication.
Where the processing went
Daily image-optimization requests, before Source
Duplicates were detected only after full processing. Moving deduplication to the second pipeline step stops them before any compute is spent.
Lookup cost per record
03 / decisions
Key decisions
- SHA-1 fingerprints instead of MD5 or SHA-256MD5 reaches a 50% collision chance at around 5 billion records, well below this catalog's size. SHA-1 pushes that past 1024 while running only about 20% slower than MD5. SHA-256 cost about 60% more, and its extra attack resistance doesn't matter for deduplication. The old MD5 value is kept so existing customers don't break.
- A new record type, not a reused oneStoring originals in the existing copies table would have been less work up front. It would also have grown that table by 30%+ and kept the slow index in the critical path. A separate table keyed by fingerprint and file type removes the index from lookups entirely.
- Phase 2: customer-defined groups, not hard-coded linksFor teams that make derived images, such as one product photo localized into many languages, I designed "source groups" where each team defines its own relationship schema. I rejected a simpler option that would have locked every group to one parent image, because that choice would be hard to reverse later.
04 / impact
Impact
- database write and storage overhead, by replacing eventually consistent secondary-index queries with deterministic key lookups
- 3× → 1×
- failed storage requests per 90 days, resolved by prefix partitioning
- ~800K
- of daily optimization requests were duplicates; they're now caught before any compute is spent
- 67%
What it unlocked
- AI and computer-vision trainingFull-resolution originals, where before only compressed copies were available
- Storefront renderingStorefronts for multiple tenants can render from the original, not a resized copy
- Compute once, inherit everywhereModeration flags, AI-generation markers and aspect ratio are computed once per original
- Complete legal take-downsEvery thumbnail, localized graphic and web format can be reached from its source
- A base for later systemsThe perceptual compression engine records its source → variant links in this layer
~/projects/amazon/one-click-takedown
Amazon · 2022–2023 · design & build
One-click take-down: cascading removal across every copy, cache and collection.
A state-driven deletion engine that removes a compromised, copyrighted or legally sensitive image and everything derived from it, from database records to edge caches, then blocks it from being uploaded again.
- per take-down, down from 10–15 min of manual tracing
- < 1 s
- take-down requests per week, North America alone
- ~8,000
- orphaned originals purged after 2+ years
- ~20M
- business goal unblocked
- $3.6B
01 / architecture
How it works
- New
- Changed
- Unchanged
- Failure path
- 1Block before deleteThe file's checksum is blocklisted first, so banned media can't be uploaded again while the teardown runs, or after it finishes.
- 2Cross-tenant discoveryEvery reference to the image is found across customer collections and snapshotted to storage before anything is deleted, for audit and resumability.
- 3Volume-aware branchingNo links: skip ahead. A few: remove them inline with a resumable index. Many: fan out to parallel batch deletion jobs.
- 4Bounded tracking, dead-letter logA tracker polls batch jobs up to 20 times and reports what failed. Every failed deletion lands in a dead-letter bucket for audit and replay.
- 5Cascade to every derivativeRelated variants are found and destroyed, the workflow confirms they're all gone, and only then removes the stored originals. Translated copies are purged automatically too.
- 6Edge to storage, rolled out safelyThe run ends with CDN invalidation. Because it handles live traffic, the new workflow was dialled up gradually, with a metric and an alarm for every failure scenario.
02 / trade-offs
Trade-offs, measured
Time to complete one take-down
Seconds, log scale
The manual process also depended on an operator finding every related file. Missing one left a legally sensitive file live.
Backfill: ~20M orphaned originals
Originals left behind by take-downs from before the cascade existed, some over 2 years old
- Partitioned SQLfind candidates in the data warehouse
- Verify liveconfirm through the live API that no active outputs remain
- Archivecopy before delete, for recovery
- Purgemultithreaded, throttled to protect live traffic
The files couldn't be fetched through any existing API, so they had to be found in the data warehouse. Each was then checked against the live system before deletion. The purge ran as a tracked change with monitoring throughout.
03 / impact
Impact
- take-downs go from a 10–15 minute manual trace to under a second, with no missed files
- 600×+ faster
- take-down requests handled automatically in North America alone
- ~8,000 / wk
- orphaned originals purged, closing a compliance risk that had been open for 2+ years
- ~20M
What it unlocked
- Legal complianceCopyright and legal removals reach every copy, so no derivative is left live
- Collections onboardingCustomers who needed take-down support could migrate to customer-managed collections
- A partner team saved 3+ weeksLocalized images are now purged automatically when their source is taken down
- AuditabilityLink snapshots, archives and a dead-letter log record exactly what was removed
~/projects/amazon/perceptual-compression
Amazon · 2024–2025 · design author & lead engineer
Perceptual compression engine: the smallest file that still looks right.
An automated optimization pipeline for marketing and storefront graphics. Each image is compressed 60 ways in parallel and scored for how it looks to a human, and the smallest file that clears a quality floor ships.
- compressions tried in parallel per image
- 60
- SSIMULACRA 2 perceptual quality floor
- ≥ 80
- peak concurrent workers, sized from first principles
- 2,500
- of marketing graphics in scope, across web, desktop and mobile
- 100%
01 / architecture
How it works
- New
- Changed
- Existing
- 1Parallel enumeration30 quality levels (99 down to 70) × chroma subsampling on and off gives 60 compressions per image, all run at once. The whole space is searched in one round-trip of about 10 s.
- 2Perceptual scoring at scaleThe SSIMULACRA 2 binary is packaged into the serverless runtime. Each worker downloads the original and its candidate, scores them, and returns size and score.
- 3Selection ruleBy default, the smallest file scoring at least 80 wins. The chosen level and score go back in the response, so marketers see the quality cost of every file.
- 4Bounded binary searchFor the ~5% of requests with a hard file-size cap, a search from Q0 up to the default level runs at most 3 iterations and stops once the range is 5 levels or fewer. This caps latency and rendering cost.
- 5Async lineageAfter the response, a background job records the original as a source and each output as a variant, using Source. Lineage adds no latency, and repeat requests can reuse results.
- 6Backward-compatible APIA new quality mode and max-file-size field on the existing optimize API. Marketing tools preview the default result through a 30-day temporary URL and set a size cap only when they need one.
02 / trade-offs
Trade-offs, measured
Sizing the worker pool
Concurrency = requests per second × jobs per request × seconds per job
10 s per job is a conservative budget; the existing optimize API's p99 was about 8 s. Estimated running cost was about $1K per 100M renderings, which made full enumeration affordable.
Which path requests take
Share of marketing image requests
The size-cap path serves a small, shrinking share of traffic, so it was designed to spend as little compute as possible rather than search exhaustively.
Two algorithms for the size-cap path
Enumeration wins on latency and binary search wins on cost. Both are designed for this path; binary search is the fallback that caps compute.
03 / impact
Impact
- marketers no longer pre-compress images by hand, which used to degrade them before upload
- 0 manual steps
- a guaranteed perceptual quality floor, with the score returned for every file
- ≥ 80 on every image
- the full 60-candidate search finishes in about 10 s at a peak of 250 requests/min
- 1 round-trip
What it unlocked
- Lighter pagesSmaller payloads and less bandwidth across web, desktop and mobile storefronts
- Personalized creativesSource-to-variant links let ranking pick between product shots and AI-generated lifestyle edits
- Reuse, not recomputeEvery output is recorded, so repeat requests can be deduplicated
- Quality you can measureEach file carries its level and score, so the cost of compression shows up in metrics

~/projects/vicino-ai-image-editor
Vicino AI Image Editor
AI-assisted image editing for Shopline merchants.
- Type
- Product · AI
- Built at
- Vicino AI
- Stack
- Links
~/projects/hackamatch
HackaMatch.com
Find hackathon teammates and project ideas at Cornell.
- Type
- Product · Community
- Role
- Founder
- Links
~/projects/favorly
Favorly
Small, everyday favors between neighbors, on iOS.
- Type
- Product · iOS app
- Role
- Co-founder
- Links
~/experience/experience.log
The path so far
-
2025-09 → 2026-02Seattle, WA
AI Research Engineer at Vicino AI
Natural-language image editing · model routing
Built a natural-language AI image editor that edits in seconds, with model routing to balance inference speed against generation cost — shipped with Shopline to 600K+ merchants.
-
2025-07 → 2025-09Seattle, WA
Founding Engineer at Bili Technology · pre-seed startup
Version control for AI agents at scale
Contributed to Parallel Agent Workspace, an AI-native version-control system, and architected PAWLite, a proof-of-concept for coordinating large fleets of agents.
-
2022-08 → 2025-07Seattle, WA
Software Development Engineer I – II at Amazon
Digital asset platform · 50B+ assets
Maintained Amazon's core digital asset repo and pipeline — 50B+ assets, 576B+ requests a year — and automated a content removal workflow that unblocked a $3.6B goal, cutting processing from 15 minutes to under a second.
-
2021-06 → 2021-08New York, NY
Automation Developer Intern at Millennium Management
Automation · internal tools
Built the Swagger-Test-Generator library for automated API test generation, and rebuilt the data comparison GUI in Angular Ant Design with two-way binding.
$ system-info
stack.json
The tools and domains behind the work in experience.log and ~/projects.
Languages
- Java
- Python
- C++
AI & research
- Generative AI
- Cost-Aware Model Routing
Systems & infrastructure
- Distributed Systems
- Concurrency
- Infrastructure
- Cloud Systems
- Data Platforms
- Version control systems
Product & tooling
- Developer Tools
- Product Engineering
- Web Development
- Automation
- Analytics
~/contact.json
Have an interesting problem?
Let's talk.